Claude is a reasoning engine, not a law library. It is genuinely useful for research work if you feed it real sources and check its output. Like any general-purpose language model, it can produce citations that are not in any source if you ask it to recall the law from memory. This guide shows the safe way to use Claude for legal research: start from the source, ground the model, reason over it, and verify every cite before filing.
Reviewed and corrected on 6 October 2026. This is general information, not legal advice; check the cited statute or opinion before relying on it.
TL;DR
- Short answer: Claude is a reasoning engine, not a legal database. Useful for research work when you ground it in real authority and verify. Verify anything it recalls from memory.
- Good at: framing the issue, summarizing sources you paste, drafting a memo from cited material, spotting counterarguments.
- Needs a source for: accurate citations, current law, and jurisdiction-specific rules. It reasons from a fixed training snapshot, not a live corpus.
- The skill is grounding plus verification. Give Claude the actual statute or opinion, ask it to reason over that text, then confirm every cite against the primary source yourself.
- Grounding lowers the error rate but does not remove it. A Stanford study of three commercial legal research tools found incorrect or unsupported answers on 17% to 33% of its test queries, against a higher rate for a general chatbot with no retrieval.
- You own the output. ABA Formal Opinion 512 puts the verification duty on you, not the tool.
You ask Claude for cases that support your argument and it returns three citations with neat parentheticals. You have not opened any of them. What are those citations?
| Claude is suited to | Claude needs your sources for |
|---|---|
| Framing the issue and spotting counterarguments | Recalling accurate case citations |
| Summarizing a statute or opinion you paste in | Knowing current, amended law |
| Drafting a memo from authorities you supply | Getting jurisdiction-specific rules right |
| Comparing two briefs you provide | Supplying authority from its own memory |
What Claude actually is
Claude is a family of large language models from Anthropic. How you reach it changes what it can do for research, so the surfaces are worth separating:
- The chat app (claude.ai), desktop, and mobile. The base assistant answers from its training, a fixed snapshot with no live legal corpus behind it.
- Web search and connectors, when enabled. Newer Claude can search the web or pull from connected tools mid-answer. That is real retrieval, but a web snippet is not a verified primary source, and general web search is not a case-law database. Claude also works inside Word, Outlook, Excel and PowerPoint (Anthropic, May 12, 2026).
- Projects and file uploads. Drop documents into a Project or a chat and Claude reasons over your files. This is grounding you control, and for most in-house work it is the safest everyday setup.
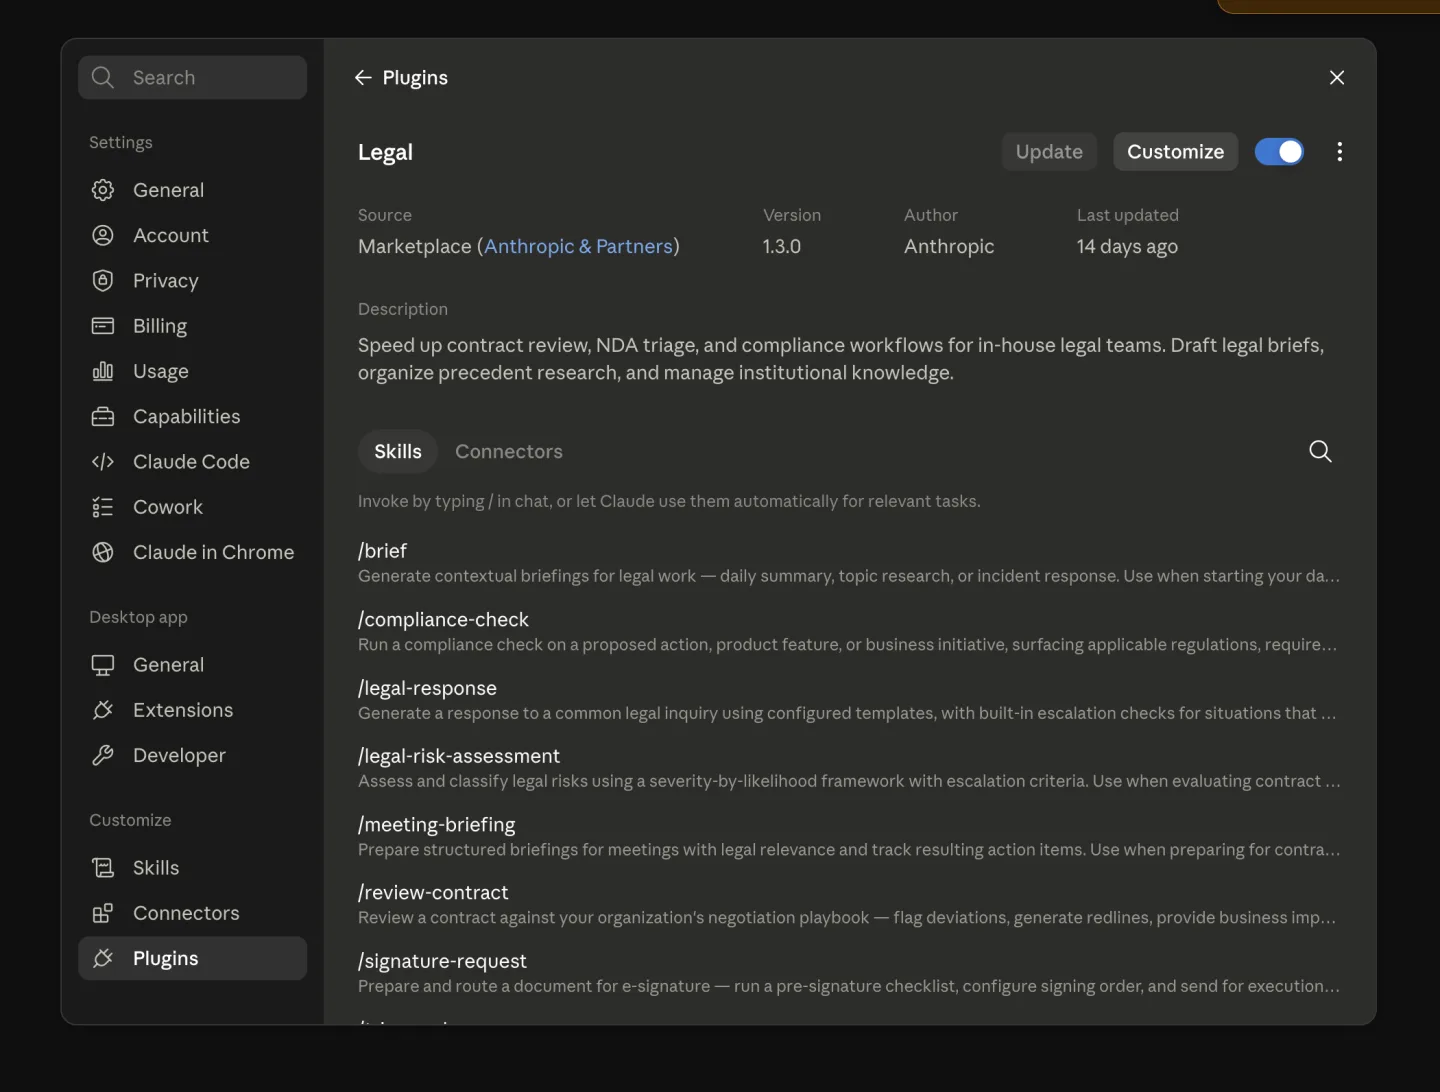
- Connectors. Claude can retrieve from a real source through the Model Context Protocol (MCP). Since 12 May 2026, Anthropic's Connectors Directory includes research connectors you add in a few clicks under Customize > Connectors. Anthropic's announcement names Thomson Reuters CoCounsel Legal, Legal Data Hunter, Midpage, Trellis, Descrybe and Free Law Project's CourtListener, among others. The plugins in the screenshot above package tasks such as litigation or contract review. The research data itself comes from a connector.
The common thread: Claude predicts the most plausible next words from patterns in its training data. Where you add a real source (a file, a connector, an MCP corpus), it reasons over something you can open. Where you do not, it guesses, and a confident guess about a case is how lawyers get sanctioned.
We covered the broader capability picture and the data-tier question in Claude for lawyers. This post is narrower. It is about the research task specifically, and the discipline that makes it safe.
What Claude is good at for research
These tasks save real time, and the verification burden stays low because you provide the raw material.
- Framing the issue. Hand Claude a fact pattern and ask what questions a court would ask, what elements a claim needs, or where the weak points sit. You are using it to think, not to cite.
- Summarizing sources you paste. Drop in a full opinion, a statute section, or a 40-page report and ask for the holding, the key dates, or a plain-English recap. It works from your text, not its memory.
- Drafting a memo from cited material. Give it the authorities you already pulled, then ask for a structured memo that reasons over them. You supply the law; it supplies the prose.
- Comparing arguments. Paste two briefs and ask where they conflict, or ask it to steelman the other side. Good for pressure-testing your own position.
Where Claude needs a source for research
The limits of a general-purpose model cluster around exactly the work that ends up in front of a court.
Recalling accurate citations. Asked for authority on a point from memory, a language model generates a citation-shaped string: a plausible case name, a court, a reporter cite in the right format. Whether a real case sits behind it has to be checked in a primary source.
Knowing current law. Claude reasons from a fixed training snapshot. Statutes get amended and cases get overruled after that cutoff, and the model has no live feed unless you give it one, so supply the current text.
Getting jurisdiction right. A general model draws on training data across states and years. Name the state and the date when you ask about a filing deadline.
The safe workflow, step by step
You do not fix hallucination with a better prompt or a newer model. You fix it with a workflow. The core move is simple: never ask Claude to recall the law, only to reason over law you gave it.
- Start from the source, not the model. Pull the statute, regulation, or opinion first, from a real database. Claude enters after you have the authority in hand, not before.
- Paste or ground the authority. Put the actual text in front of the model. Now its answer is anchored to a document you can open, not to a pattern it half-remembers.
- Ask Claude to reason over it. Have it apply the pasted rule to your facts, summarize the holding, or draft from the material. Keep the job to reasoning and writing.
- Verify every cite against the primary source. Open each citation and read the actual text. If Claude surfaced a case you did not supply, treat it as a lead to check, never a fact.
- Never file an unverified citation. If you cannot open the source and confirm it says what the draft claims, it does not go in the document. No exceptions under deadline.
Ways to ground Claude
Grounding means giving the model real law to work from instead of letting it free-associate. Three options, from simplest to most reliable.
Paste the sources yourself. The manual version. You find the statute or opinion, paste it into the chat, and ask Claude to work over that text. Cheap, works today, and it forces you to have the primary source open already. The limit is scale: you can only paste what you have already found.
Add a research connector, or connect your own MCP server. The Model Context Protocol lets Claude call out to real tools and corpora during a chat. Instead of guessing a citation, it retrieves from an actual source and answers over the result. You can add a research connector from Claude's Connectors Directory (Customize > Connectors) or connect a server of your own. Retrieval narrows the grounding gap for the research half of the job. It does not remove the need to read the source. We walk through the setup in using Claude for US legal research with MCP.
Use a grounded legal AI. A purpose-built tool retrieves over real opinions and statutes, then answers on top of them, so each cite links back to a source you can open. Grounding lowers hallucination risk because the model has something real to anchor to. It does not remove the verification duty; it makes verification a click instead of a research project.
Can Claude tell you if a case is still good law?
Not from memory. Cases are overruled after Claude's training snapshot, and a model has no way to know. The Stanford paper's own example is a tool that stated a standard from a case the Supreme Court had since overruled. A citator is a separate job: it tracks later history and how other courts treated the case.
Some connectors in Anthropic's directory touch it. Anthropic describes Descrybe's connector as able to "check treatment status" and Thomson Reuters' CoCounsel Legal as grounded in KeyCite. Midpage's documentation says its treatment data "is not a complete good-law check". Free Law Project said on 12 May 2026 that it is building a free, open citator and that an MCP integration is on its roadmap. Whatever you use, read the later history in the citator yourself before you rely on a case.
Prompt patterns that reduce hallucination
Prompting is not a cure, but a few habits keep the model honest.
- Give it the text, then ask it to quote. "Using only the statute I pasted, quote the exact subsection that sets the deadline." Constraining it to your source blocks free invention.
- Name the jurisdiction and date. "Delaware law, current as of the pasted document" beats a bare question. It stops the model from blending states and years.
- Ask for uncertainty out loud. "If the pasted material does not answer this, say so instead of guessing." Claude tends to hedge when told it may, which is what you want here.
- Forbid unsourced citations. "Do not cite any case I did not provide." If it still surfaces one, you know to treat that as a lead to check, not an answer.
- Separate drafting from sourcing. Let Claude draft the argument from your authorities, then do the cite-checking as its own pass, against primary sources, not the model.
A worked example
Say you need the pleading standard for a Rule 12(b)(6) motion to dismiss.
The unsafe prompt, and why it burns you:
"What's the standard for a 12(b)(6) motion, with the key cases?"
Claude answers fluently and names cases, probably Bell Atlantic Corp. v. Twombly, 550 U.S. 544 (2007) and Ashcroft v. Iqbal, 556 U.S. 662 (2009), which are real. But it may also attach a pinpoint cite, a parenthetical, or a third case that is subtly wrong or wholly invented, and it reads just as confidently as the accurate parts. On the page, you cannot tell the fabricated cite from the real one.
The grounded version, after you have pulled and pasted the opinion:
"Here is the text of Ashcroft v. Iqbal that I pasted above. Using only
this opinion, summarize the plausibility standard in three sentences and
quote the exact language it comes from. Do not cite any case I did not
provide."
Now the output is anchored: a short summary plus a verbatim quote you can locate in the text you supplied. The cite-check becomes one pass: open Iqbal, confirm the quoted language exists and says what the draft claims. If Claude names any case you did not paste, that is a lead to verify in a database, never a fact to file.
The honest limits and your verification duty
None of this makes Claude a database. Grounding and good prompts lower the hallucination rate; they do not eliminate it, and the numbers above show even dedicated tools miss. So the last line of defense is always you.
ABA Formal Opinion 512 (July 29, 2024) is the ethics guidance that applies the Model Rules to generative AI. It says a lawyer's reliance on, or submission of, a generative AI tool's output without an appropriate degree of independent verification or review could violate the duty of competence under Model Rule 1.1. The amount of checking depends on the tool and the task, and a task like generating ideas may need less. Before you file, the opinion says to review the output, including every citation to authority, and correct errors (its discussion of Rules 3.1 and 3.3).
We translate the full opinion into plain English in our ABA Formal Opinion 512 guide. The stakes are not hypothetical. In the case that put this on the map, Mata v. Avianca (S.D.N.Y. 2023), two lawyers and their firm filed an opposition citing six non-existent decisions generated by ChatGPT and stood by them after the court questioned them. Judge Castel sanctioned them under Rule 11, or alternatively the court's inherent authority, with a $5,000 penalty and notice letters to the plaintiff and to each judge falsely named (No. 22-cv-1461 (PKC), S.D.N.Y. June 22, 2023). The court itself said there is "nothing inherently improper about using a reliable artificial intelligence tool for assistance", but that the rules put a gatekeeping role on attorneys to ensure their filings are accurate. The lawyers failed at that job: one of them asked a language model to supply the law and quoted only the excerpts it generated, with no full text of any of the fake decisions in hand. Our AI hallucination sanctions tracker logs the growing list of US cases that followed. This article is general information, not legal advice, so check your own state bar guidance too.
The verdict
Is Claude good for legal research? Yes, for the research work, no, as a source of law. Used as a reasoning engine over authority you supply and verify, it is a fast, capable partner for framing issues, summarizing sources, and drafting memos. Used as a memory to recall citations, it is a liability that produces convincing fakes.
The skill is not finding a smarter model. It is feeding the model real law and checking its work. Ground it, prompt it to quote rather than recall, and verify every cite against the primary source.
For the US statutes, regulations and court rules these laws sit in, see the US primary law API.
FAQ
Is Claude good for legal research? For the research work, yes. For sourcing the law, no. Claude is strong at framing issues, summarizing sources you paste, and drafting memos from cited material. Recalling citations and current law from memory is outside what it is built for, so supply the sources. Use it to reason over authority you supply, then verify every cite yourself.
Does Claude cite real cases? Only if you check. Asked for supporting authority from memory, a language model predicts a citation-shaped string, and whether a case sits behind it has to be confirmed in a primary source. Treat any case it surfaces on its own as a lead to check, not a fact.
Can Claude do legal research on its own? The chat assistant by itself predicts citations rather than retrieving them, so research needs a source behind it. Connecting it to a research connector from Anthropic's directory, or to an MCP server of your own, adds real sources and narrows the gap. Either way, you confirm every cite against the primary source before relying on it.
How do I stop Claude from hallucinating citations? You cannot fully, so you build a workflow around it. Paste the real authority, constrain Claude to quote only your source, name the jurisdiction and date, and forbid it from citing anything you did not provide. Then cite-check against primary sources as a separate pass.
How does Claude relate to Westlaw or Lexis for research? They solve different problems. Westlaw and Lexis are research databases. Claude is a reasoning and drafting assistant with no built-in corpus. Verification applies to every tool. Use Claude to reason over sources, a database to find and confirm them.
Do I have to verify AI output if the tool is grounded? Yes. Grounding lowers the hallucination rate but does not remove it, and ABA Formal Opinion 512 puts the verification duty on you regardless of the tool. Grounded retrieval makes checking a click instead of a rebuild, which is the real benefit.
Can I paste client documents into Claude for research? Only on a plan whose data terms fit the sensitivity of the matter. Read the current terms for your plan before you paste anything confidential, and consider anonymizing it first. We cover the consumer-versus-business split in is Claude private for legal work.
What is the safest way to use Claude for legal research? Start from the source, not the model. Pull the authority from a real database first. Paste or ground it, then ask Claude to reason over that text. Verify every cite against the primary source. Never file a citation you have not confirmed.
Last updated: October 2026
New legal AI guides, weekly.
Further Reading
- Can Claude Search Statutes and Regulations? How to Check the Answer
- Claude Fable 5 and Legal AI: What Its Benchmark Records Actually Mean
- Claude for Legal: What In-House Teams Need to Know
- Perplexity AI for Lawyers: What It Can and Cannot Do
- Firecrawl's Government & Legal Index: What It Takes to Index US Law
- Lexis+ AI, CoCounsel and Westlaw AI: Is There an API?

Co-Founder & CEO · Attorney
Arshita leads product and strategy at Vaquill AI, the US primary law data API. As an attorney, she decides which law we carry, how each section is sourced and cited, and what legal AI and compliance teams need from the data.